Jiaqi Li's Homepage

jiaqili3[at]link.cuhk.edu.cn
I am a third-year Ph.D. student at the Chinese University of Hong Kong, Shenzhen (CUHK-Shenzhen), SDS, supervised by Professor Zhizheng Wu. Before that, I received B.S. degree at CUHK-Shenzhen.
My research interest includes speech language models, text-to-speech synthesis, and neural audio coding. I am one of the main contributors and leaders of the open-source Amphion toolkit. My recent work includes FlexiSLM, a spoken language model with dynamic and controllable frame rates, as well as DualCodec and FlexiCodec for low-frame-rate speech generation.
news
| Aug 21, 2026 | Our SimulS2ST-Omni paper was accepted to EMNLP 2026 Main Conference! |
|---|---|
| Aug 21, 2026 | Our FlexiSLM paper was accepted to EMNLP 2026 Main Conference! |
| Apr 26, 2026 | I presented our FlexiCodec paper at ICLR 2026 in Brazil. 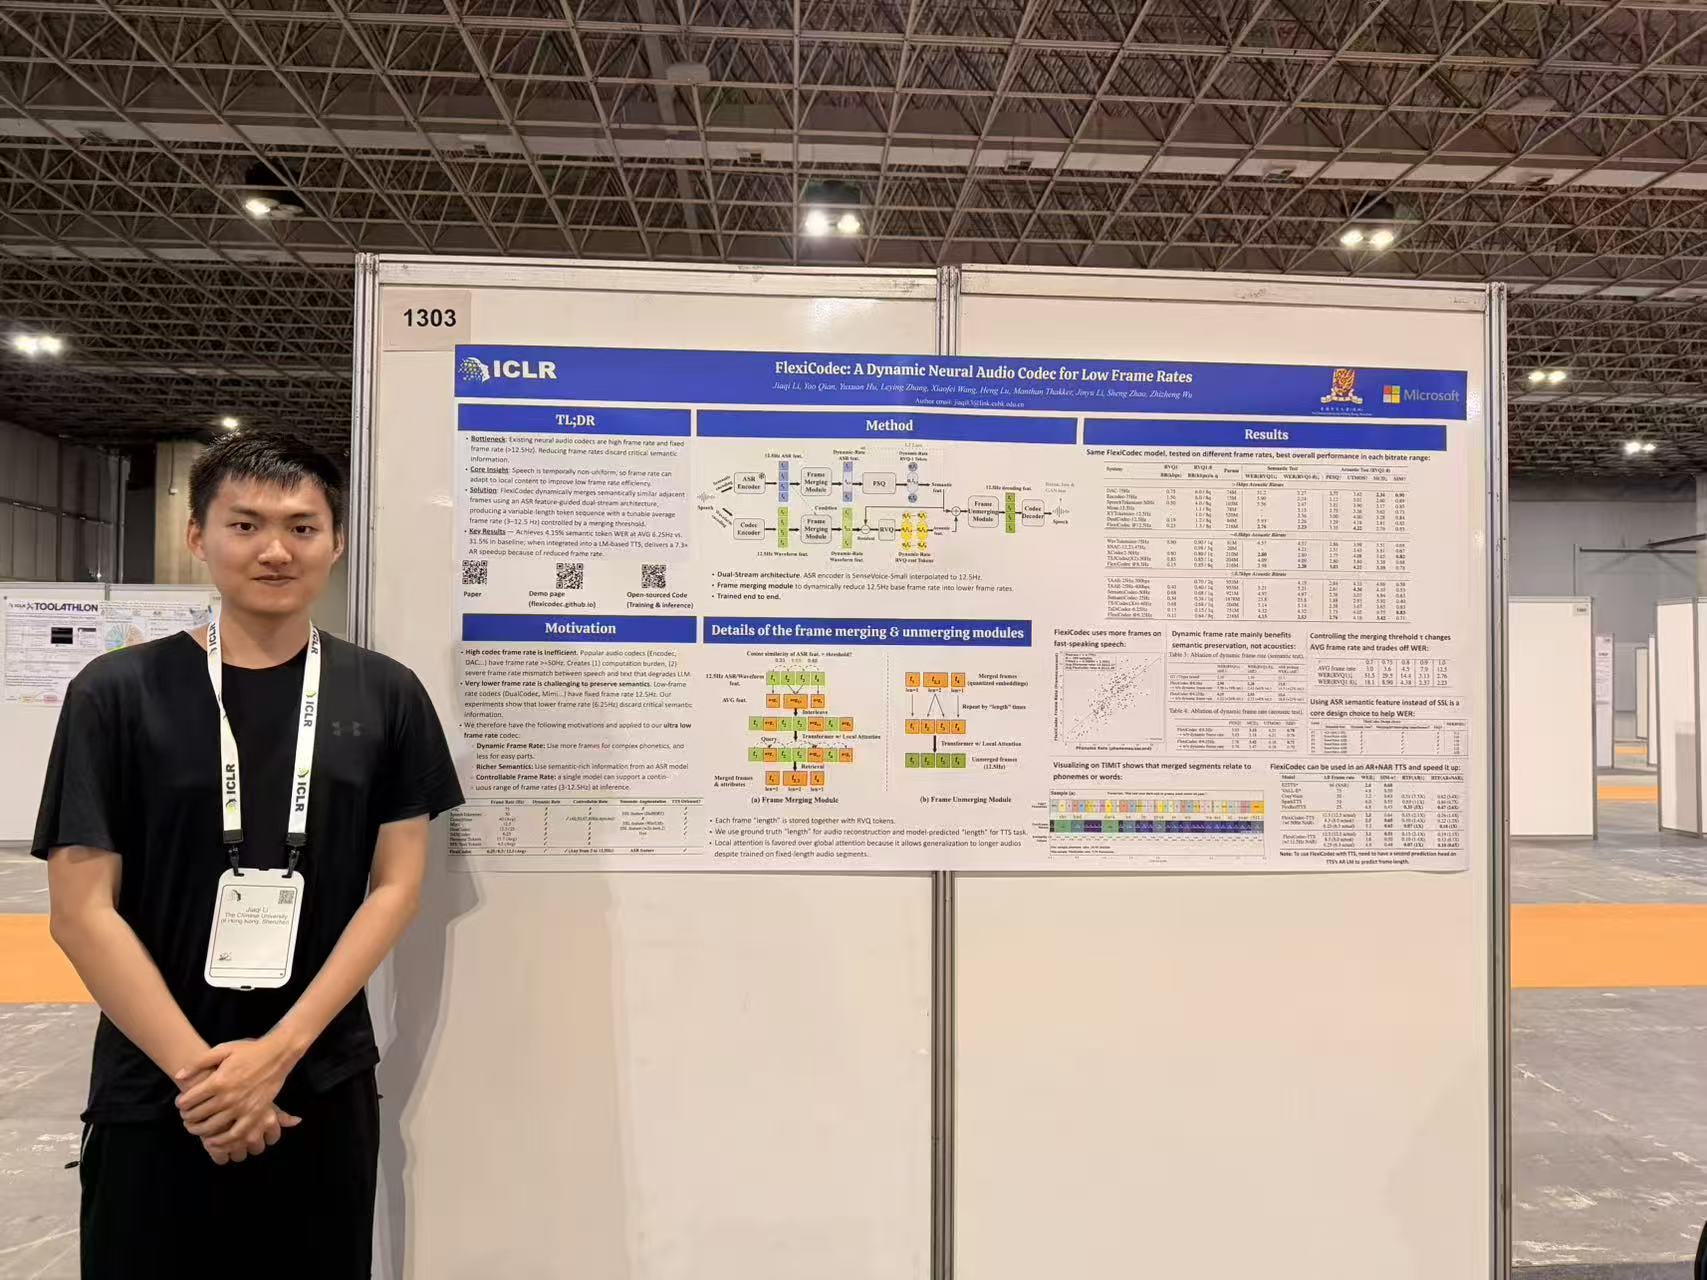 |
| May 17, 2025 | Our DualCodec paper was accepted to InterSpeech 2025! |
| Feb 01, 2025 | We released the Amphion v0.2 technical report, summarizing our development of Amphion in 2024. |
| Dec 03, 2024 | I presented our new paper, Investigating neural audio codecs for speech language model-based speech generation in SLT 2024. 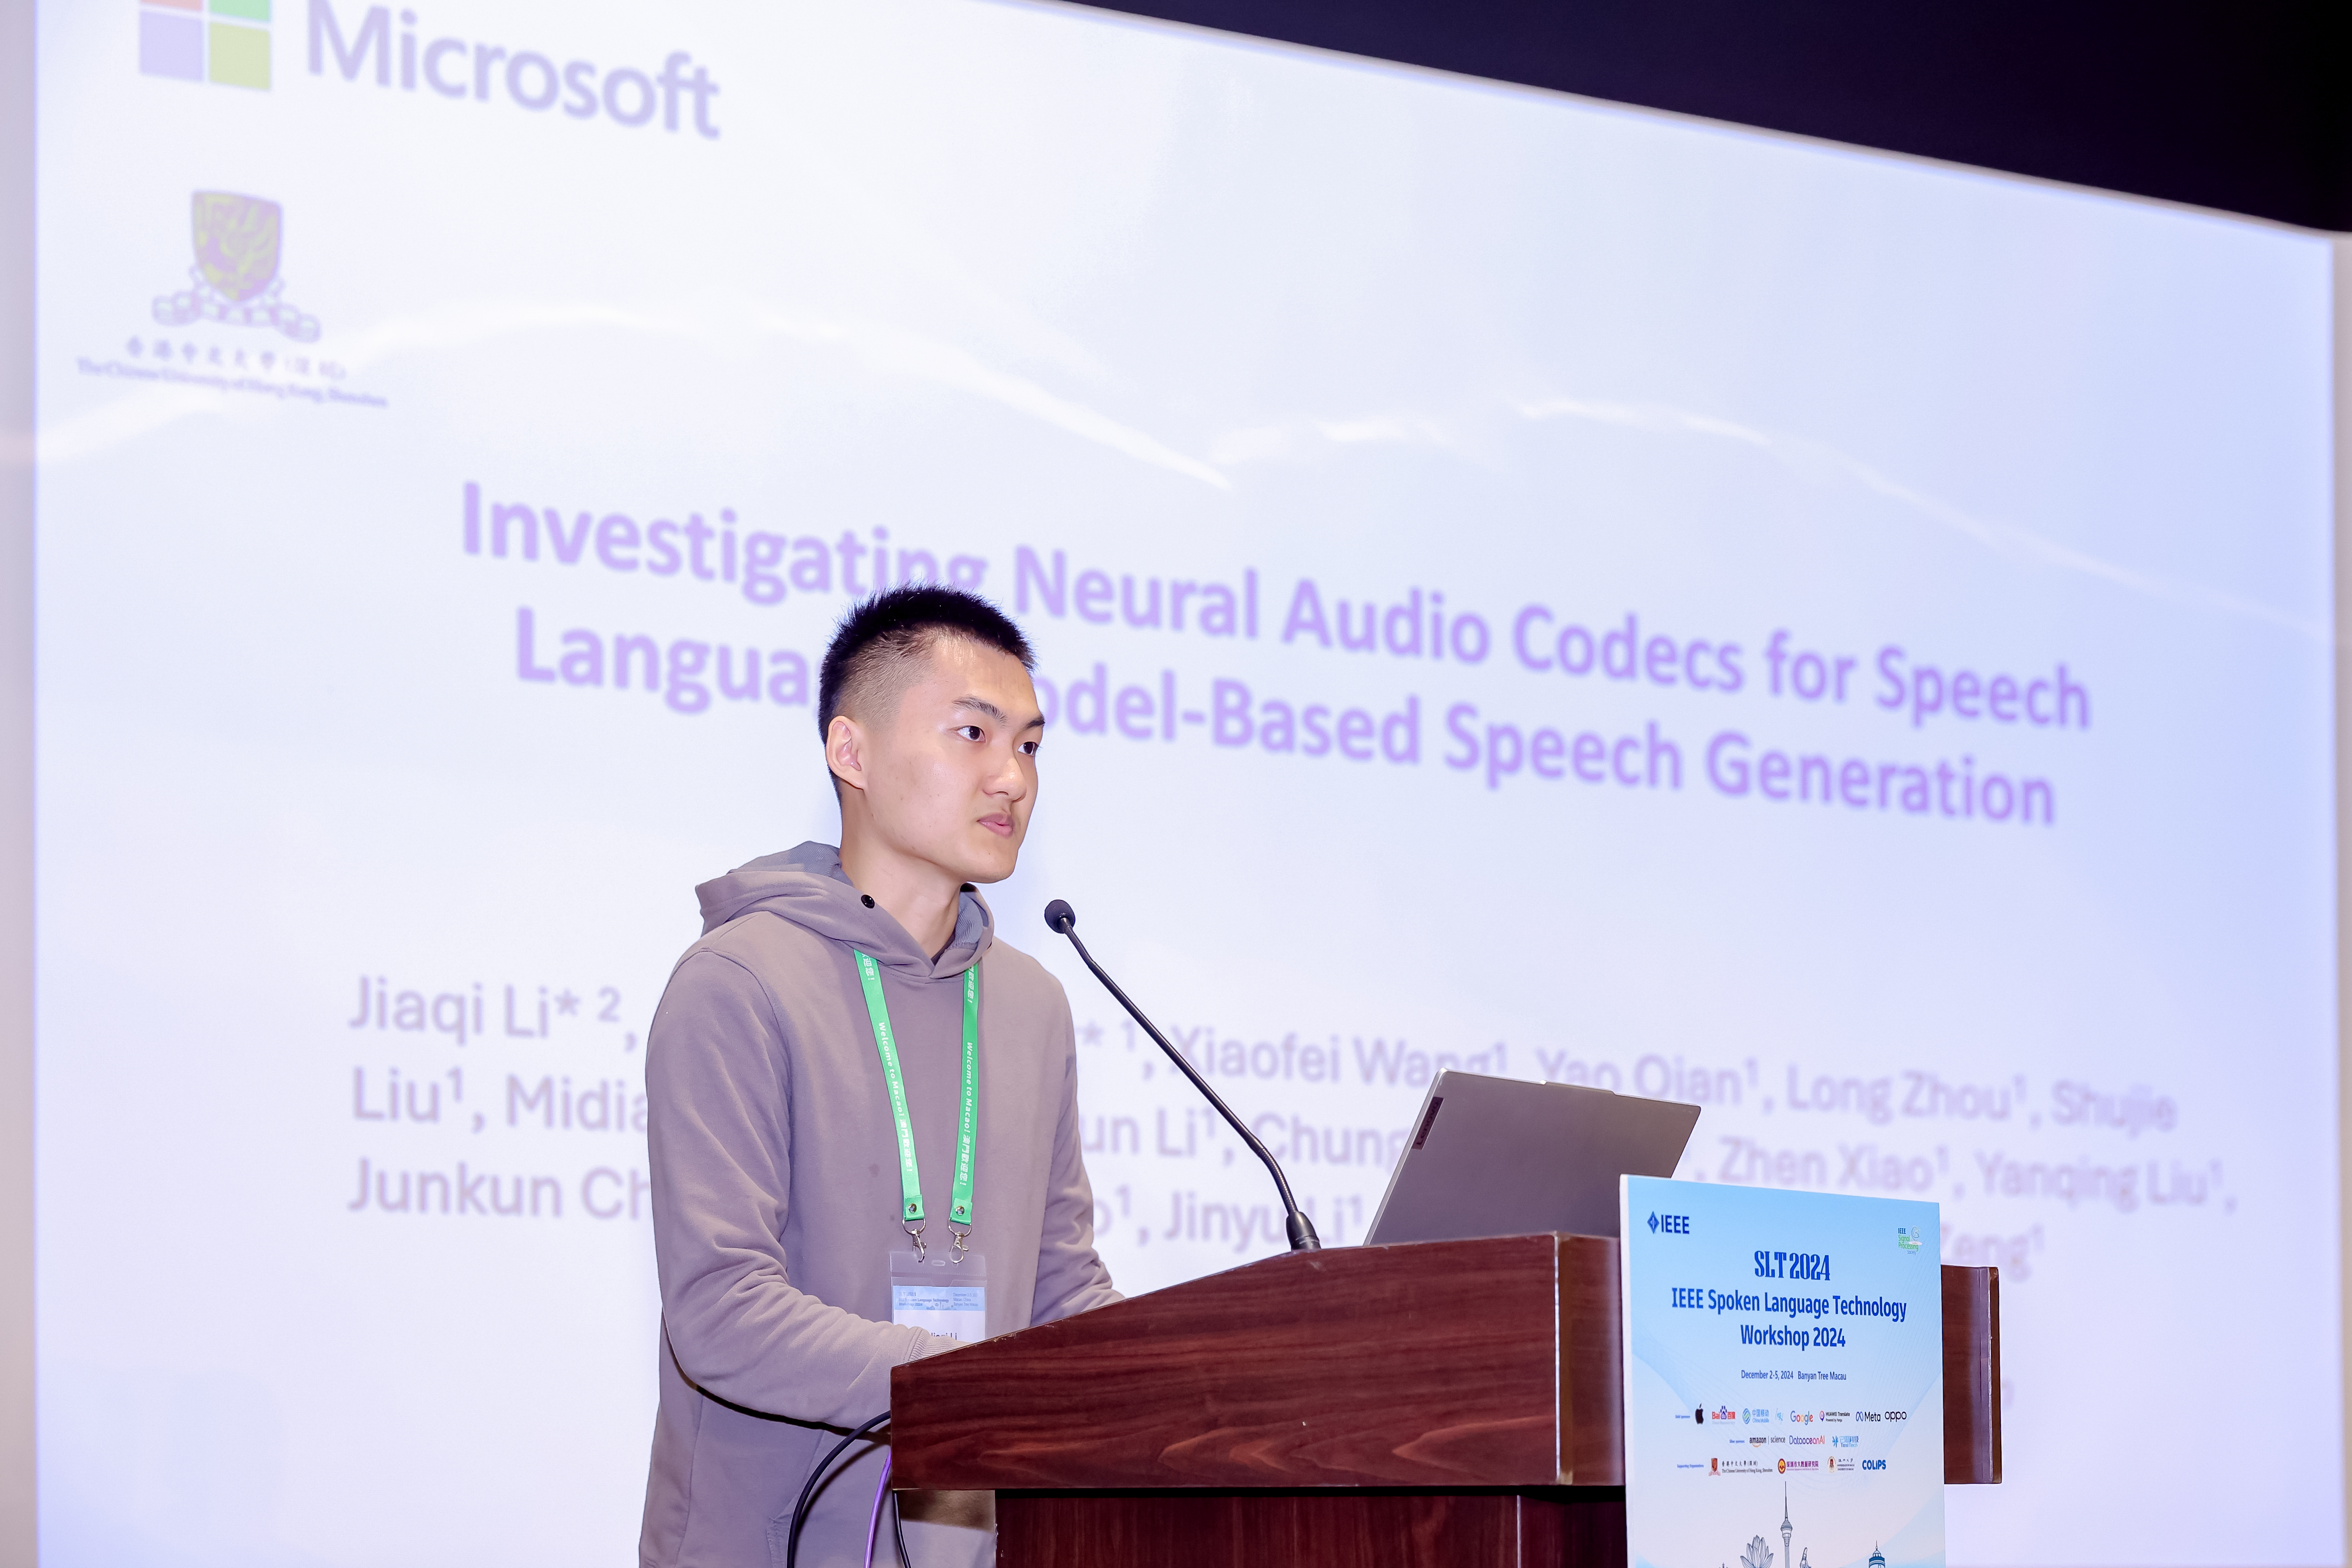 |
| Aug 25, 2024 | 🎉 Our papers, Amphion and Emila, got accepted by IEEE SLT 2024! |
| Jul 28, 2024 | 🔥 We released Emila: An Extensive, Multilingual, and Diverse Speech Dataset for Large-Scale Speech Generation, with 101k hours of speech in six languages and features diverse speech with varied speaking styles. |
| Apr 19, 2024 | I presented our paper, An initial investigation of neural replay simulator for over-the-air adversarial perturbations to automatic speaker verification in ICASSP 2024 in Korea!  |
| Nov 26, 2023 | 🔥 We released Amphion v0.1  , which is an open-source toolkit for audio, music, and speech generation. |
selected publications
- EMNLP 2026FlexiSLM: A Spoken Language Model with Dynamic and Controllable Frame RatesIn Proceedings of the 2026 Conference on Empirical Methods in Natural Language Processing, 2026TL;DR: We introduce the first spoken language model with dynamic and controllable frame rates for speech input and output.
- EMNLP 2026SimulS2ST-Omni: Data-Efficient Streaming Speech-to-Speech Translation via Explicit Trajectory SupervisionIn Proceedings of the 2026 Conference on Empirical Methods in Natural Language Processing, 2026TL;DR: We enable data-efficient long-form streaming speech-to-speech translation with joint text-code trajectory supervision.
- Tech ReportOverview of the Amphion Toolkit (v0. 2)arXiv preprint arXiv:2501.15442, 2025TL;DR: This is the technical report for the second version of the Amphion toolkit.
- SLT 2024Emilia: An Extensive, Multilingual, and Diverse Speech Dataset for Large-Scale Speech GenerationIn 2024 IEEE Spoken Language Technology Workshop (SLT), 2024TL;DR: We collect a 100k hours in-the-wild speech dataset for speech generation.
- SLT 2024Amphion: an Open-Source Audio, Music, and Speech Generation ToolkitIn 2024 IEEE Spoken Language Technology Workshop (SLT), 2024TL;DR: We develop a unified toolkit for audio, music, and speech generation.